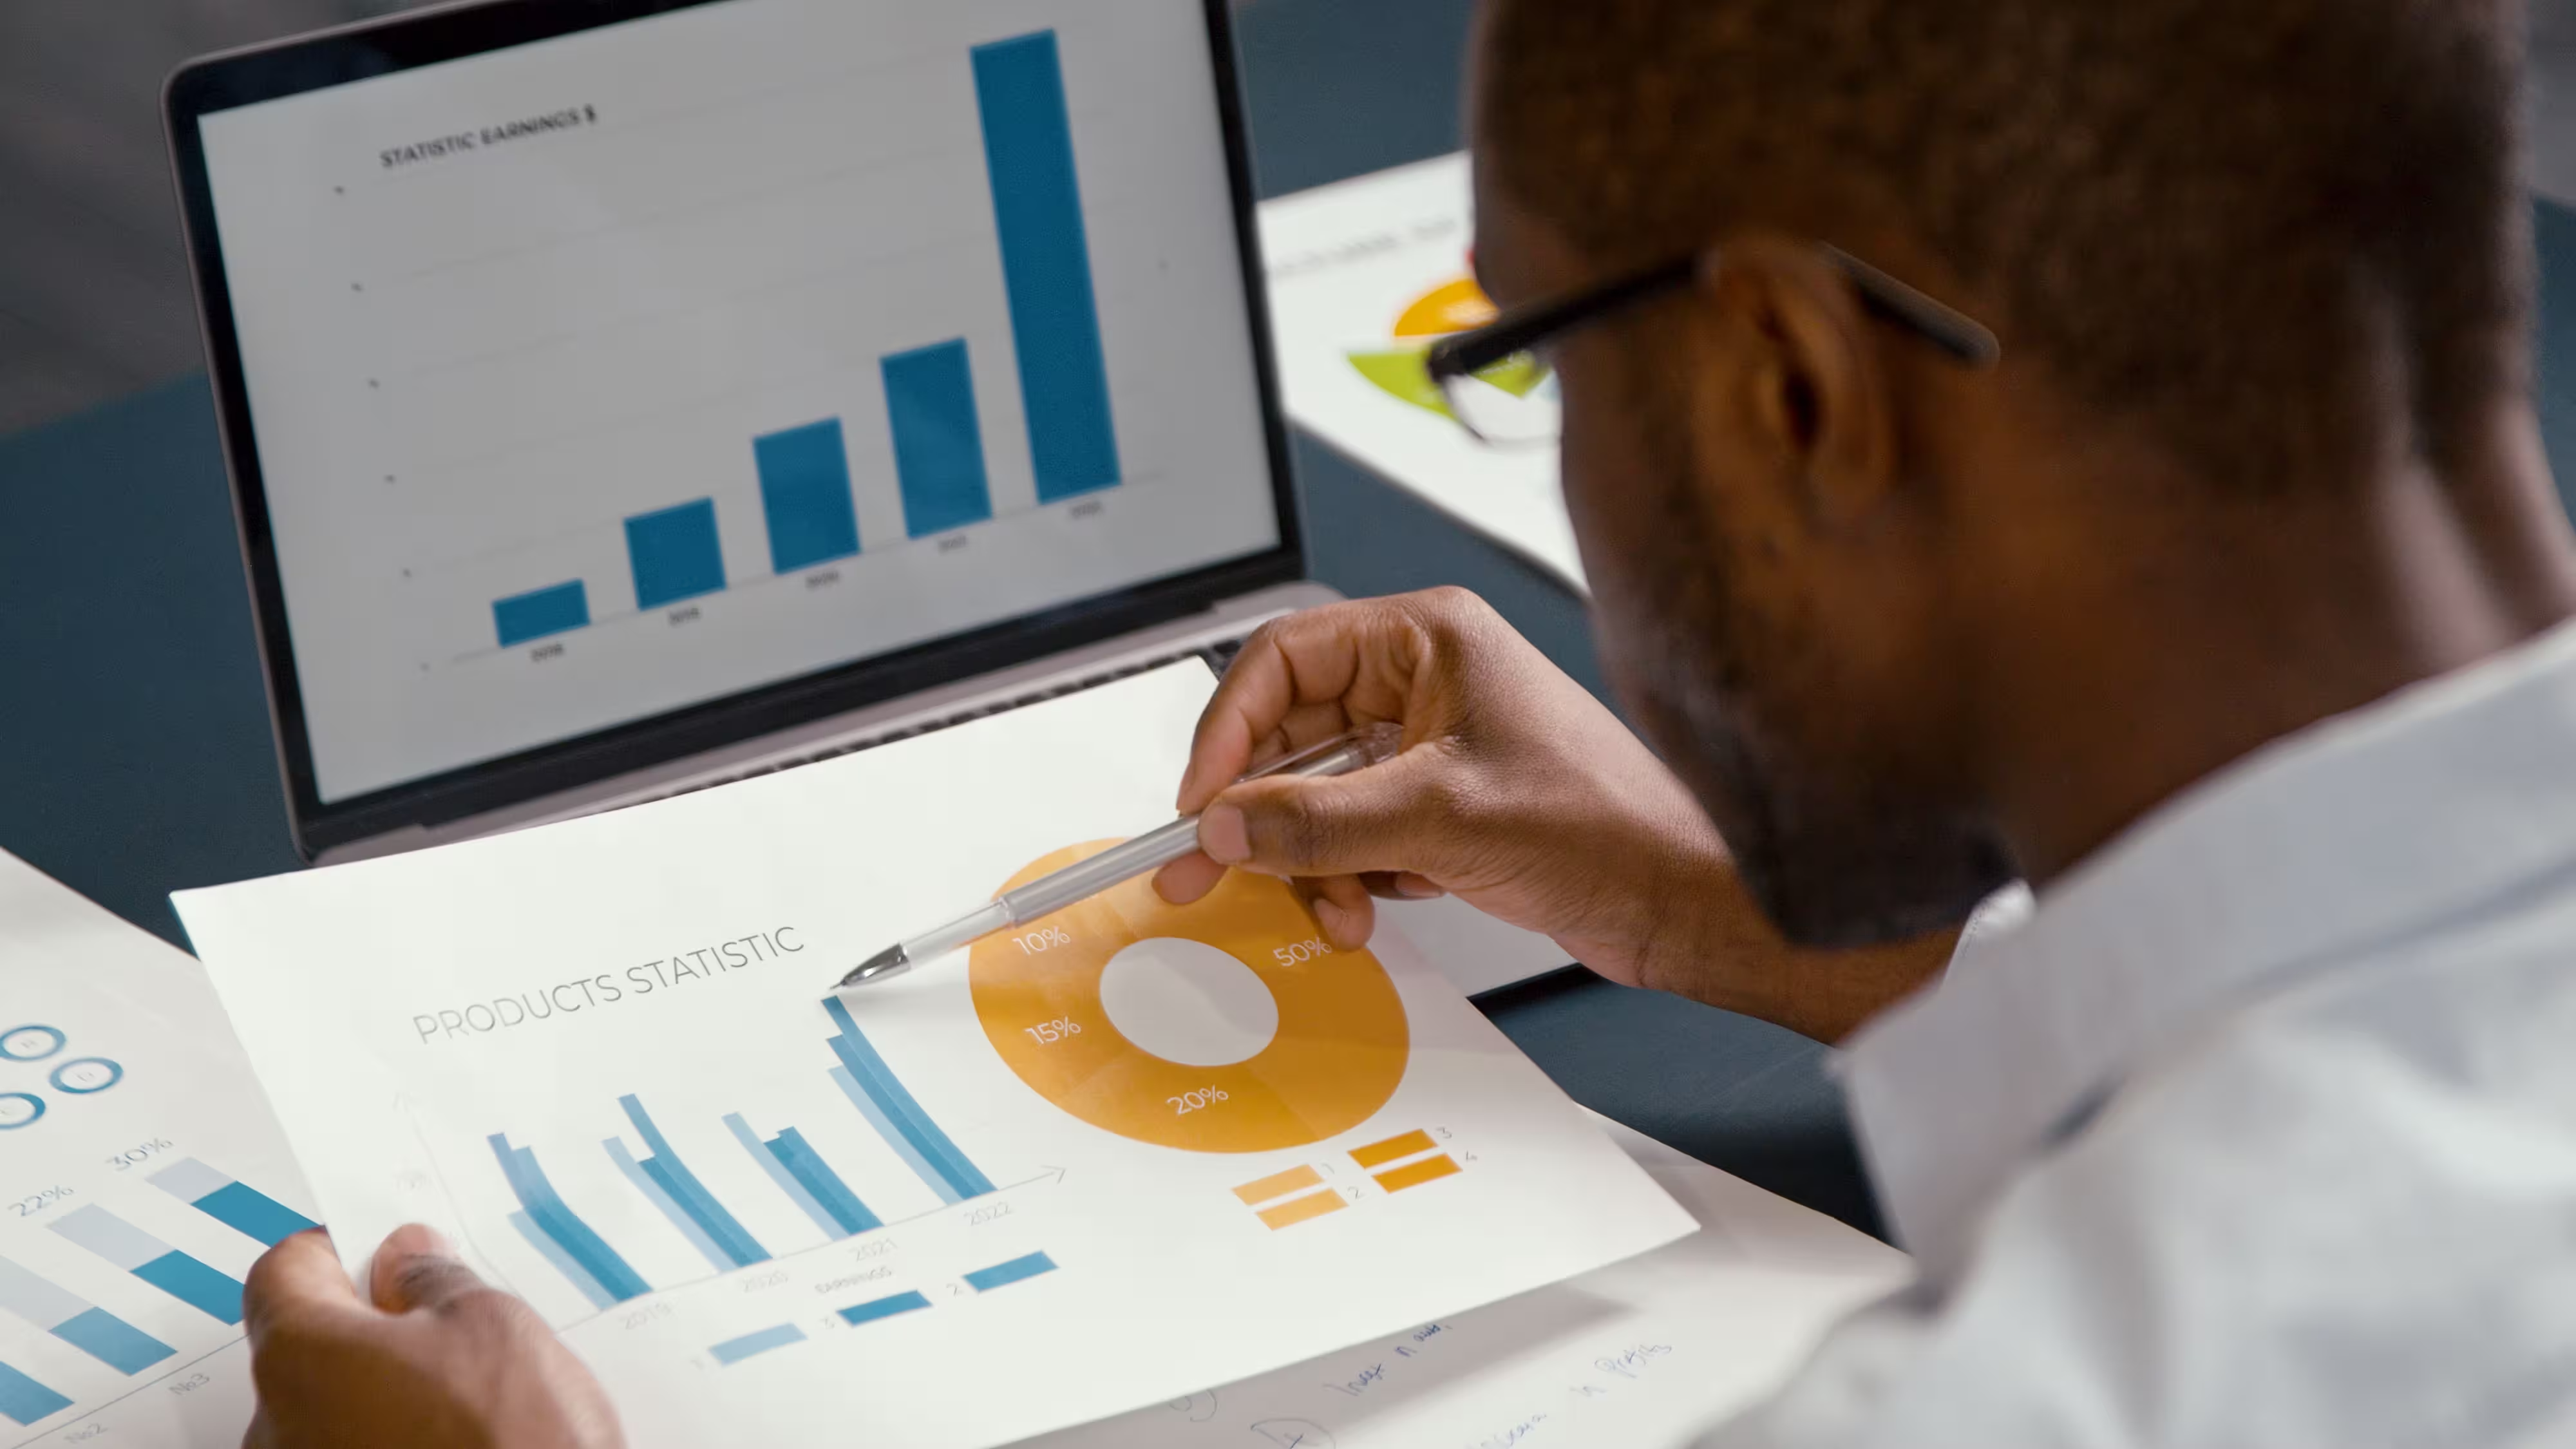


A retail pricing platform converts price recommendations, transaction data, and cost data into an attributable margin-lift estimate by modeling the baseline that would have sold without the price change. Validated against a control group, that estimate gives finance a basis for approving, scaling, or rejecting the investment.
The decision is not whether the platform produces a new price. The decision is whether the retailer can distinguish pricing impact from changes in demand, assortment, inventory, promotions, seasonality, and competitive conditions.
What Decision Should a Retail Pricing Platform Prove?
Retail pricing platform ROI is credible when incremental net margin is measured against a defensible counterfactual rather than against an unadjusted prior period. The result should show what changed, why it changed, and whether the margin gain justified implementation and operating costs.
Rules-based tools, elasticity-driven optimizers, and pricing modules embedded in broader planning suites represent different approaches to pricing workflow, but a buyer should evaluate each approach against the same financial question: can the organization connect a pricing action to realized margin after volume, cost, inventory, and promotional effects are accounted for?
Define the Profit Equation
Use net margin as the primary outcome. A practical equation is: net margin equals gross margin on the priced item minus discount cost, plus affinity margin earned on related items, minus margin lost to cannibalization and promotional marketing cost. Finance can extend this with variable fulfillment and payment costs where they are tracked. Gross margin can remain a useful executive measure, but it should not hide discount and secondary effects.
Separate three layers in the business case: realized margin lift, avoided margin leakage from toxic promotions and mispriced items, and platform cost. The first two describe operating impact; the third determines whether the impact becomes an acceptable return on investment.
Why Do Common Pricing Lift Analyses Mislead Buyers?
Retail price-lift analysis becomes misleading when the comparison period is treated as the counterfactual without accounting for other changes. A prior-period comparison can combine pricing impact with weather, holidays, competitor moves, stockouts, marketing activity, and changes in product availability.
Difference-in-differences is a useful analytical design because it compares change in a treated group with change in a comparable untreated group. It does not remove every source of bias; its value depends on treatment assignment, pre-period comparability, contamination controls, and consistent outcome definitions.
Sales volume also needs separate treatment. A price increase that raises unit margin but reduces units can improve or weaken total net margin depending on the size and economics of the volume response. Reporting only average price or revenue leaves that decision unresolved.
Which Measurement Criteria Separate Credible Lift From Noise?
A pricing measurement framework separates credible lift from noise by defining the outcome, comparison group, observation window, exclusions, and decision threshold before results are reviewed. That prevents the measurement design from changing after an attractive or disappointing result appears.
Use an Operational Measurement Rubric
- Outcome definition: Use net margin per item, store, category, or customer segment as the primary measure, with affinity and cannibalization netted in, and units, revenue, and sell-through as supporting measures.
- Comparison design: Use a treatment group and a control group of store clusters or price zones with comparable assortment, channel, competitive intensity, and demand characteristics. As a working rule, require at least two comparable pre-treatment observation periods before relying on a difference-in-differences estimate.
- Data quality: Treat an unmatched cost, promotion, inventory, or return record as an exception rather than silently assigning a value. The exception rate should be reported beside the lift estimate.
- Decision threshold: As a practical evaluation heuristic, classify a result as decision-ready only when the direction of margin movement remains stable across segment cuts and across more than one time period. This is a governance rule, not a claim about statistical certainty.
The rubric should also include statistical significance when the test design supports it. A significance test alone does not establish commercial value; the result needs an effect estimate, a sample definition, a breakdown of which drivers moved demand, and a predicted-versus-actual check across time periods.
How Should Teams Implement a Control-Group Measurement Design?
A control-group design estimates pricing impact by comparing treated performance with the performance of a comparable group that did not receive the pricing change. It complements the platform’s modeled baseline: the model estimates what would have sold without the change, and the control group confirms it. Together they support a clearer margin attribution than a simple before-and-after report.
Start by defining the unit of treatment: store cluster, price zone, region, channel, or customer segment. Individual SKUs make poor test units because related items lift or cannibalize one another. Then document the treatment date, price rule, eligible population, exclusions, cost basis, promotion status, inventory state, and outcome formula. The data model should preserve the recommended price and the executed price so the analysis can distinguish recommendation from execution.
Use a pre-period balance check before interpreting results. Compare demand direction, average units, net price, cost, stockout exposure, promotion frequency, and assortment across treatment and control groups. As a working rule, a material imbalance should trigger re-matching or a narrower test rather than a confident lift claim.
For implementation, feed the pricing platform the retailer’s product master, transaction history, cost data, inventory positions, and any available competitor pricing, and run promotions and approvals through the platform’s own calendar and workflow. Confirm that rejected recommendations, manual overrides, delayed changes, and cross-channel price gaps are captured because execution variance can otherwise appear to be model performance.
What Trade-Offs Should Buyers Accept?
Pricing measurement improves decision quality by making the counterfactual explicit, but it adds governance, data engineering, and operating discipline. A platform is not a substitute for clean cost data, controlled execution, or an agreed financial definition of value. To successfully integrate these tools, organizations must accept that the initial phase requires a significant investment in data hygiene. Without unified data feeds, the platform’s outputs remain theoretical. Furthermore, the shift from traditional “gut-feel” pricing to simulated, measured price changes requires a cultural pivot; your teams must be willing to accept that some price changes and promotions, once measured, will rate neutral or margin-negative.
This is not a failure of the software, but rather a necessary step in refining your pricing strategy to align with actual consumer elasticity. Additionally, you must be prepared for the internal friction that occurs when automated recommendations conflict with established merchandising intuition. Establishing a clear governance framework—where human experts review automated suggestions—is essential to maintaining trust. Finally, recognize that the complexity of your retail environment (e.g., omnichannel fulfillment, regional competition) will dictate the granularity of your measurement. Do not aim for perfect precision in your first month; instead, focus on directional accuracy.
Over time, as your data models mature and your cost-tracking becomes more granular, you can iterate toward more sophisticated attribution methods, ultimately building a robust, finance-approved engine for margin growth.
- Infrastructure prerequisites: Successful implementation is fundamentally blocked if the retailer cannot join price, cost, unit, inventory, promotion, and transaction records at a consistent, granular level. Without a unified business key, the platform cannot calculate true net margin at the SKU-store level.
- Operational vigilance: Ongoing monitoring is mandatory. Factors such as stockouts, markdowns, customer returns, unexpected product substitutions, and manual pricing overrides can drastically skew results if not properly flagged and accounted for in the model.
- Strategic trade-offs: While a controlled platform evaluation demands significantly more preparation and time than a legacy period-over-period report, the payoff is a significantly higher level of confidence. By making the counterfactual explicit, you provide the finance department with a transparent, defensible basis for separating genuine pricing impact from broader market volatility.
Ready to Validate a Pricing Investment? Map your transaction, cost, inventory, promotion, and execution data to the measurement rubric, then request a platform demonstration using your own margin definition and test design. Start the evaluation and request a demo.
What Should a CFO See in a Pricing Lift Business Case?
A CFO-ready pricing lift business case links an attributable margin result to implementation cost, operating cost, execution coverage, and the conditions under which the result could change. The presentation should make the calculation reproducible without requiring the CFO to interpret model terminology.
Present the modeled baseline margin, realized margin under the price change, control-group movement, estimated net incremental margin after affinity and cannibalization, units and revenue impact, exception volume, and the cost of the platform and operating team. Show margin lift and volume movement together so a positive price effect is not mistaken for a positive business effect.
Use a sensitivity view for alternative cost assumptions, excluded transactions, inventory constraints, and different segment definitions. The recommended decision can then be stated plainly: scale the pricing rule, continue testing, revise the data design, or reject the investment because the measured economic benefit does not cover the total cost.
PriceSmart supports this with a weekly recommendation refresh, exception-based alerts, plan-versus-actual tracking, and reporting on prediction accuracy, so the lift calculation stays reproducible as prices change.